Strangler Pattern in PHP: Cutting Maintenance from 70% to 5%
Two of our clients' PHP products spent over 70% of their time and budget on maintenance. Today it’s around 5%.
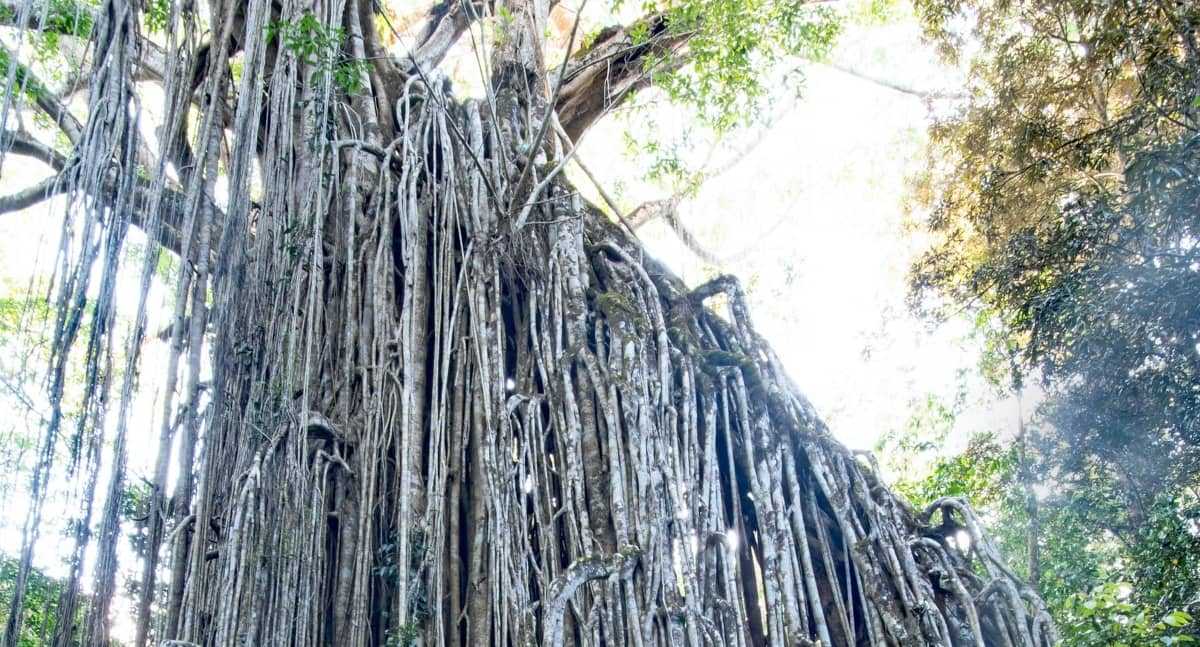
This is a photo I took during my trip to Peru, and it explains how we did that.
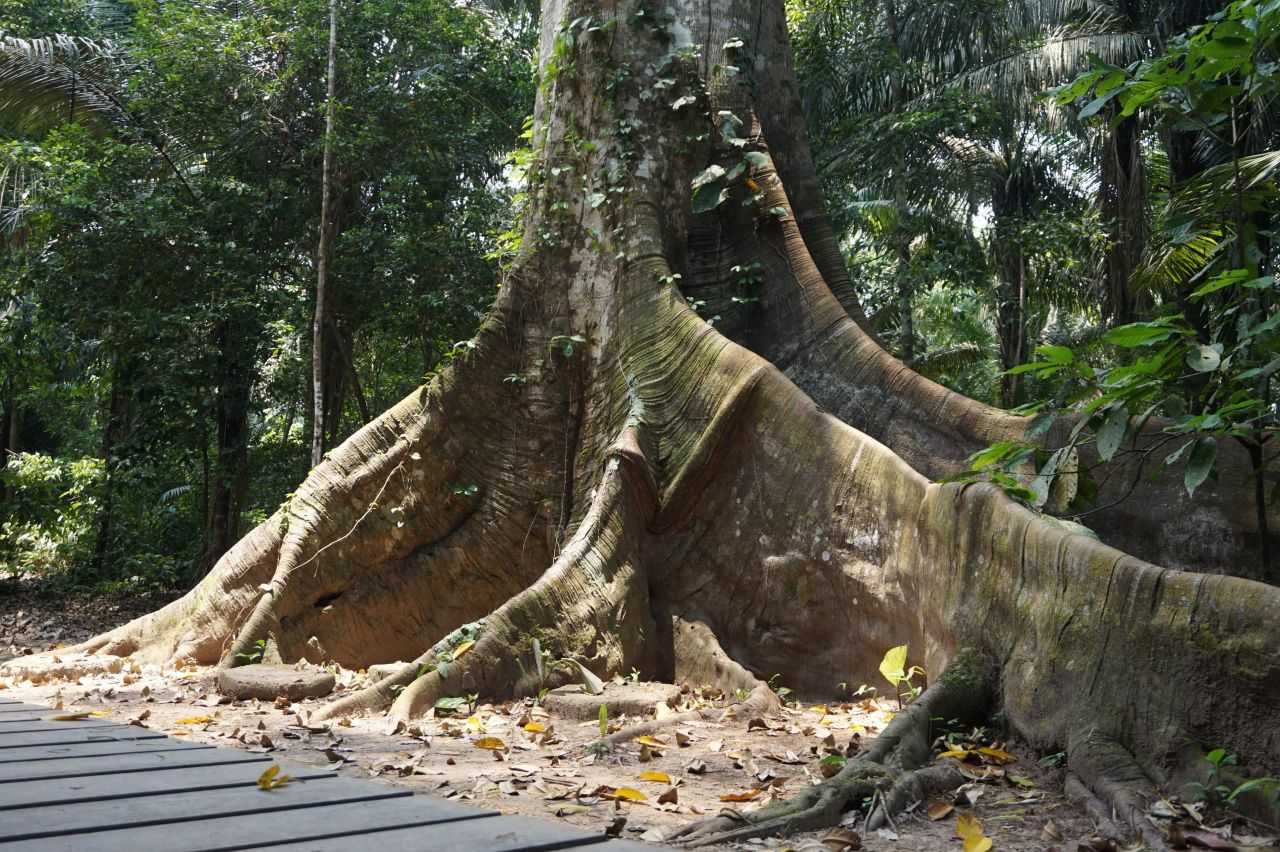
It’s a matapalo, a strangler fig, in the Peruvian Amazon. Those huge fins spreading across the ground aren’t a trunk. They’re roots. The tree started as a seed in the canopy of another tree, sent roots down around the trunk, and fed off its host until it no longer needed it. The host is gone.
What struck me, standing in front of it, is that you’d never know. It doesn’t look like something that replaced something else. It looks like it has always been there.
Short answer: what is the strangler fig pattern?
The strangler fig pattern is a way of replacing a legacy system gradually. You build new functionality around the old application, route more and more traffic to the new parts, and retire the old code piece by piece until the old system can be switched off. There is no big-bang rewrite, no cutover weekend, and no downtime while the product keeps running.
For teams and businesses responsible for large, revenue-critical PHP applications, that makes it a practical modernization strategy when technical debt is already slowing delivery. Instead of freezing feature work for a full rewrite, you keep shipping, reduce risk, and move maintenance effort out of the legacy codebase - often from the majority of engineering time to a small fraction once the old parts are gone.
Martin Fowler saw the plant in Queensland in 2001 and later named a software pattern after it. He first called it the Strangler Application, then renamed it Strangler Fig, partly for the plant and partly because “strangler” alone sounded too violent. His original write-up is still the clearest explanation there is.
Peru never softened anything. The park sign next to the tree says Ficus sp. Matapalo, which means “tree killer”. It describes the plant as “surrounding, strangling, killing the tree it leaned on, until it reaches the light.”
In software, the killing is the point. You want the old system gone. What follows is how to do it safely in a PHP application: incrementally replacing legacy parts, routing requests through facades, handling data synchronization, reducing maintenance overhead, and deciding when this approach is better than a full rewrite.
Almost every article describes the middle
Search for the strangler pattern and you’ll find dozens of diagrams: a facade, a router, old and new boxes side by side, an arrow moving from left to right. That is the middle of the story. We’ve written plenty about the middle ourselves. Michał’s practical guide to the strangler pattern walks through the mechanics in detail, and his pros and cons article covers the trade-offs.
Far fewer people show the end. Michał Romańczuk described the day he finally deleted the /legacy directory in Strangler Pattern in practice. I now have two products that look like it.
Both arrived at the same starting point. If you’ve worked on a long-lived PHP application, you’ll probably recognize it:
- years of accumulated decisions made by different people under different pressures,
- a framework version nobody dared to upgrade,
- a team that was quietly afraid of its own deploy button.
We never rewrote either one. There was no feature freeze and no big-bang release. New code grew around the old code, piece by piece, while the products kept shipping and customers kept paying.
Today there is almost nothing left of the original applications. To the customer they look the same, with the same workflows and the same logins. Underneath, it is completely different software.
Like the tree, you wouldn’t know by looking.
The numbers
I pulled them last month:
- Before: over 70% of time and budget went into maintenance.
- Now: around 5%.
- The other 95% goes into product.
PHP upgrades, once a quarter-long project with a budget line and a risk register, are now a ticket someone picks up on a Tuesday.
Before anyone asks: 5% isn’t low because we stopped maintaining. It’s low because work that used to take a week now takes an hour.
For context, in the guide Michał estimates 6 to 18 months of incremental migration for a medium-sized SaaS product. Our two took about four years, and feature work never stopped during that time.
Why we didn’t rewrite the legacy system
The instinct when a codebase becomes untouchable is always the same: start fresh, do it right this time. I’ve watched that fail too many times. My colleague described why it is usually a trap. For a year or more you pay for two systems, the old one that earns the money and the new one that earns nothing. The old one keeps changing, so the new one is always chasing a moving target.
Here is how the three realistic options compare, as laid out in the guide:
| Approach | What it is | Risk | Initial cost | Total cost |
|---|---|---|---|---|
| Full rewrite | Rebuild everything, then switch over | Very high | Very high | Medium to high |
| In-place refactoring | Change code directly inside the monolith | Low to medium | Low | Very high |
| Strangler Pattern | Run two systems side by side with controlled routing | Low | Medium | High |
If your target architecture is microservices, the Strangler Pattern gives you a gradual approach to transform a monolith safely, one slice at a time.
I’ll be honest, as Michał is in the guide: running two systems in parallel genuinely costs more than building one new system once, if the rewrite actually ships. The rewrite number is the one most likely to be wrong, because it quietly assumes an outcome that often doesn’t arrive.
The strangler approach changes the economics in another way. Every slice you replace is already in production, already serving users and already paying for itself. If priorities change halfway, you stop with a better system than you started with.
The playbook
I won’t pretend there is a magic recipe, and every codebase is different. But these principles run through all our strangler projects.
1. Make change safe before you make change
Before replacing anything, we make sure we’ll know when something breaks, because careful planning is what makes this migration process smooth despite the usual challenges. That means characterization tests around the critical business flows, error monitoring (we deploy Sentry early), and CI/CD with a rollback path we trust.
This isn’t a nice-to-have. As we explained in the PHP upgrade cost breakdown, the biggest cost driver of an upgrade isn’t the code change but testing what breaks afterwards. The same is true of every modernization step.
2. Put a dumb facade in front
The facade is the single entry point that decides whether a request goes to the old code or the new. Keep it boring. In most of our projects it’s nginx or Traefik doing path routing, and URL-based routing covers about 95% of cases. Complex logic belongs in the services, not in the proxy. The first step is invisible to users: route 100% of traffic through the facade and confirm nothing changed, while the existing system continues to operate during the transition.
3. Pick the first slice carefully
A good first candidate is low risk, well isolated, clearly bounded and worth proving. Just as important is knowing what not to rewrite. As Michał puts it in Monolith to Microservices, there is no reason to touch a component that works well, never changes, or has a codebase so bad that the risk outweighs the return.
In the Clean Model Always Wins case study, we started with a product catalogue because it was slow, sat in a key step of the buyer journey, and was easy to model. Another good example is migrating an e-commerce platform’s Payment Service when it is sufficiently bounded. In some cases, inventory is also a sensible early slice. It delivered return on investment early, which is what keeps the business behind a long migration.
This is where migrations quietly go wrong. Teams spend months rebuilding a system and end up with the same data model in newer syntax. The fix is a real anti-corruption layer, a boundary where legacy quirks get translated once and never leak into the new domain.
There’s a simple test from the guide: grep your new domain code for the word legacy. Every hit outside the ACL is a leak. We ran it on the catalogue project years later and the domain model came back clean.
4. Keep the data sync boring
Data synchronization sounds like it needs serious infrastructure, but it’s crucial during migration to keep operations consistent. In the catalogue project it didn’t, and the implementation stayed simple. Legacy stayed the only writer and the new app the only reader. We accepted a few minutes of delay. The whole sync was database triggers, a queue table and a cron job, with no Kafka and no Debezium, and it ran reliably for years. When the boundaries are right, the machinery between them can stay boring. The same step-by-step sync approach also applies in cloud migration when legacy workloads are moved gradually.
5. Ship every slice, then delete the old code
A strangled piece that lives on a branch isn’t strangled, it’s a risk. Each slice goes to production, and shipping it separately makes troubleshooting easier because bugs are isolated to the specific new service or feature being migrated. We often used feature flags and canary releases, switching users over gradually, though that can also introduce coordination issues during rollout. Then comes the step most teams skip: deleting. Leave the old code behind and you maintain two systems forever, and the old system is only fully replaced after those migrated slices prove stable in production. The guide calls this the “short-lived forever” trap, where temporary integrations quietly become permanent.
Deleting can also be a pleasant surprise. Using usage tracking in the project from Strangler Pattern in practice, we found that some features the client considered crucial were not used by anyone. We hid them behind flags, waited to see if anyone complained, and removed them. The cheapest code to migrate is code you don’t need.
And through all of it, we kept shipping features. Modernization ran in parallel with product work, never instead of it.
Why maintenance falls so dramatically
It isn’t one clever trick. It’s the compound effect of removing, one by one, everything that made maintenance expensive:
- No tests, so every change is a gamble. With tests, a change is a quick check.
- An ancient framework, so every dependency is blocked. On a current framework, updates flow.
- Inconsistent code, so every fix is made five times. With one consistent approach, you fix it once.
- Fear of deploying, so releases are rare and large. With confidence, releases are small and boring.
Each item makes the next one cheaper. After a while the system stops resisting you, and a week of work turns into an hour.
The real blocker isn’t PHP
We’re running a survey on what blocks PHP upgrades. We already have over a hundred responses, and the most common answer isn’t a PHP problem at all.
It’s the lack of automated tests. Teams have no way to know what an upgrade will break, so nobody risks it.
That matches what I wrote in The Real Cost of Ignoring PHP Updates: teams usually delay updates for practical, not careless, reasons, and thin test coverage turns fear into a legitimate blocker.
None of those blockers exists on these two products anymore. Not because we fixed the upgrade, but because over four years we removed everything that made upgrades hard, while shipping features the whole time.
You don’t solve an upgrade problem by planning a better upgrade. You solve it by building a system where upgrading is boring.
Is the strangler fig pattern right for you?
It works best for large PHP projects with real accumulated debt, revenue-critical systems where downtime costs money, and teams that must keep shipping during modernization of both code and architecture. It’s a poor fit for very small apps you could rewrite in a few weeks, or for apps already on a modern framework without enough mess to repay the overhead of running two systems.
Two more things worth knowing:
- It doesn’t mean microservices. Moving from a chaotic monolith to a modular monolith works just as well, and for a single team it’s usually the better choice. A move to microservices can introduce operational challenges, which is why this pattern works best as a gradual approach. Monolith to Microservices explains when splitting makes sense and when it doesn’t.
- Sometimes you can’t strangle, but you can tame. If every new feature touches most of the system, there may be no slice small enough to replace. In Legacy code: strangle or tame?, Krzysztof shows how domain events and command handlers let new features use legacy code without refactoring it first.
And if you ever have to stop, you’re not stuck. In the catalogue project the migration was paused for business reasons, and nothing broke. Every strangled piece kept running in production and the legacy app kept handling the rest. With a rewrite, that same decision leaves you with a neglected old product and a half-built new one.
Where to start on Monday
- Measure your maintenance share. Look at the last three months and estimate what percentage of engineering time goes into maintenance, bug fixing, upgrades and “keeping the lights on”. You’ll probably be surprised.
- Check your safety net. How long does it take to find out whether a change broke something? If the answer is “we deploy and see”, start here.
- Put the facade in place. One reverse proxy, 100% of traffic through it, zero functional change.
- Pick one slice. Choose a small, well-bounded piece of functionality that changes often or hurts often.
- Replace it, ship it, delete the old version. Then do it again.
- Automate the boring parts. Static analysis, dependency updates and compatibility checks in CI are what turn upgrades into Tuesday tickets.
If you’d like an outside view of where your seams are, our PHP application review is a good place to begin.
Conclusion
The matapalo doesn’t look like a replacement. It looks like it was always there. That is what good modernization feels like from the outside: same shape to the customer, completely different software underneath, and no day on which everything stopped.
Over 70% on maintenance, down to around 5%. Upgrades as a Tuesday ticket. The other 95% going into product.
So I’ll leave you with the question I now ask everyone: what share of your engineering time goes into maintenance right now? Most people have never measured it, and the number surprises them.
If you’d like to talk about what this could look like for your application, get in touch, or talk with our AI modernisation advisor.
FAQ
What is the strangler fig pattern in software development? It’s an approach to replacing a legacy system incrementally - an implementation pattern for modernizing an existing system. New code is built around the old application, traffic is gradually routed to the new parts, and old components are removed once they’re no longer used. Martin Fowler named it after the strangler fig plants he saw in Queensland, Australia.
Can the strangler fig pattern be used with PHP applications? Yes. A reverse proxy such as nginx or Traefik gives you a natural place to send some routes to new code and others to legacy code. It works with Symfony, Laravel and custom frameworks.
How long does a strangler fig migration take? It depends on the size of the system. Michał’s guide estimates 6 to 18 months for a medium-sized SaaS product. Our two products took about four years, with features shipping throughout. Visible wins usually come in the first few months.
Is the strangler fig pattern better than a full rewrite? For business-critical products, usually yes. You avoid paying for two systems at once, you deliver value with every slice, and you can stop at any point with a working product. A full rewrite can still be right for very small projects.
Do I need microservices to use strangler pattern? No. Microservices are one possible destination, not a requirement. When they are the goal, the Strangler Pattern is a gradual approach rather than a one-time cutover. A modular monolith is often a better target, especially for a single team.
Can I use it with little or no test coverage? Yes, but start by adding characterization tests around the critical flows and set up monitoring first. Missing tests are the most common blocker we see, and they’re the first thing to fix.
Why do PHP upgrades get so expensive? Mostly because of missing automated tests, outdated frameworks and dependencies, and inconsistent code. Fix those and an upgrade stops being a project and becomes routine work. See our PHP upgrade cost guide.